Only worked with the bpm generator today. Started out writing a function to compare a generated bpm to beats found from a file. It worked, but not particularly helpfully. If the downbeats are correlated exactly, it's easy to tell if a file matches or not. If it is off by, say, an eighth note, then two identical beats will nonetheless return with no matches. It is possible to run and re-run matches to get the best data, but it takes up a lot of processing time and may not be necessary if the most occurring spaces is used by default. I've left the function in the program uncalled, for now.
After a few hours of testing, I discovered that my bpm generator was constantly getting laggy data. On a few songs, it was accurate, but on most, the beat it created was not the same as the beat in the song. I figured out that, the faster a song is, the less accurate the program can determine it's bpm. Why? Because of the spacing.
See, if I took every sample and tested if they were a beat, I would be able to tell exactly how far apart the beats are. However, in order to tell if they are a beat, I must take more than one sample at a time; in this case, 1024 samples. The relation of the spacing to the bpm is an inverse function, so the smaller the beat distances are, the larger the bpm discrepancies. For example, the program can accurately generate any bpm less than 80, give or take a beat. From 80 to 95, it skips two or more beats; any higher, and it skips more. By 151, it skips by ten, and above that is unhelpful.
However, I have a few plans to combat this. In cases where the bmp is not exactly spaced by sample size, the most occuring two (or top one and three) spacings should be next to each other, because sometimes the spacing is closest to one, and sometimes the other. Finding the average of the two will lead to a more accurate bpm. At least, that's the theory. As of right now, the only song I've had time to test it on has become more inaccurate. Tomorrow will be more testing to correct this.
13 July, 2010

Axtell's Notes: July 13
Today I finally got to all those things I'd said I'd fix about two weeks ago. When somethings scrolls, the units scroll too. When something zooms in, it no longer prints data points in the border. FFTGUI once again has a compare function, and now it can compare any number of windows. I updated the Readme and Help files and continued general cleanup of all files.
I also played with weightings. The advanced menu now has 4 options (A,B,C and C modified.) C modified should only be used when trying to get something like a cymbal crash or hand clap. Those sounds tend to not get found by FFTs because they have strange waves. The modification is simply lets quieter peaks be graphed. So in Shave and a Haircut the last note (a cymbal crash) is visible, but in Maple Leaf Rag almost all the inaudible spill is visible.
C-Weighting, in general, seems to be the best. A-Weighting seems to miss a lot of data. As an example, here's a file made by Tayloe. It's two tones fading in and out. It was made to test the color spectrum.
Rainbows are still being tweaked. I discovered that they weren't properly fading because when I had adjusted the scaling, I hadn't adjusted the colors. Oops. Also, as can be seen in the screen shots, instead of all peaks past a certain point being red, the highest peaks now go from red to magenta.
I also played with weightings. The advanced menu now has 4 options (A,B,C and C modified.) C modified should only be used when trying to get something like a cymbal crash or hand clap. Those sounds tend to not get found by FFTs because they have strange waves. The modification is simply lets quieter peaks be graphed. So in Shave and a Haircut the last note (a cymbal crash) is visible, but in Maple Leaf Rag almost all the inaudible spill is visible.
C-Weighting, in general, seems to be the best. A-Weighting seems to miss a lot of data. As an example, here's a file made by Tayloe. It's two tones fading in and out. It was made to test the color spectrum.
 Pretty - A-Weighting
 Pretty - B-Weighting
 Pretty - C-Weighting
Rainbows are still being tweaked. I discovered that they weren't properly fading because when I had adjusted the scaling, I hadn't adjusted the colors. Oops. Also, as can be seen in the screen shots, instead of all peaks past a certain point being red, the highest peaks now go from red to magenta.
12 July, 2010
7/12/10 Daily Journal of AT
After a bit of a break, I'm back for the seventh week of the internship. Most of my work today was with Beat Finder. I got the data about as clean as it will ever be, relatively speaking, and moved on to finding the beats per minute of any given song.
Essentially, the BPM, or beats per minute, are a way of recording the tempo of a song, originally for use with a metronome. A moderately speedy song would have a BPM of 120, or contain 120 quarter notes per minute (or two a second). Slower songs have a lower BMP, and faster songs have a higher BPM.
The path to getting BPM from beat data is a bit complicated. First, the program starts with an array of beats and silences. Each point of data is equivalent to 1024 samples long. The program measures the space between each beat, and stores it in a new array. The array is sorted, then each of the lengths are translated into BPM (by being multiplied by their sample size (1024), divided by the number of samples per minute (44100*60), then inverted).
The frequency of each bpm is totaled, and put into another new array. Right now, the program finds the top three occurring BPMs, the average, and the average after outliers are removed. With the test files I've used, the most occurring and the second average tend to be the same number, so it is slightly redundant. However, if a song should change tempo, or has an irregular back beat, this extra data may become necessary.
Overall, this seems fairly accurate. However, when testing the BPM by creating a new beat file, it tended to lag in relation to the song. I'm going to try to fix this tomorrow, then move on to either fixing the file generator or moving on to a new feature.
Axtell's Notes: July 12
Today was a lot of testing of the weighting functions. I made a tester class that prints the curve of A-, B-, C- and my own tweaked weightings on top of each other in different colors so I could see what looked best. I've added a constant to both the B- and C- weightings to neaten them up, and I am playing with combining them to get more precise window. Here we have Maple Leaf Rag with each of the weightings:
 Maple Leaf Rag - A-Weighting
 Maple Leaf Rag - B-Weighting
 Maple Leaf Rag - C-Weighting
 Maple Leaf Rag - B/C-Weighting
There is almost no difference between the B-weighted and the B/C-weighted spectrogram.
I made the advanced menu so now the buffer size and weighting controls are less available unless you really want to change them. I, once again, updated the rainbows. I started to go through each class and clean up, comment, get rid of what's unnecessary, etc. I'll finish the clean up tomorrow and continue to play with the weightings. I also need to update the readme and help files.
09 July, 2010
Axtell's Notes: July 9
I started off with a project that I thought would take all day, but that was done before lunch; I switched everything from a 3D array to a HashTable of 2D arrays so that access would be faster. Most full length songs run in under a minute now. I also cleaned up the code quite a bit to get rid of warnings (mostly redundant casts and unchecked instances).
I then spent all day making a browse option, or trying to. It doesn't work as of yet. The idea is that you should be able to use any sound file from anywhere on the computer, so I'm making a window that is like any Open Document GUI. It shows the directory and you can open or collapse folders and select the desired file and use that one. There are two problems with this. First, it prints the whole pathname of each file or folder which makes it too long to practically read, but JTree names it using File.toString() so I need to find a way print only the end of the pathname. The other problem is that this only works once. If you click browse and chose a filename that works fine, but try to do it again without restarting the program and it gets NullPointerExceptions.
While showing the professor how the GUI works, I found why my code has been printing a lot less than it used to. Where I get the dB of the file, I've been multiplying by 0.775 instead of dividing. This hasn't been not on files such as a440 because 0.775 is close enough to 1 that it didn't make a difference. On full songs though, it was very noticeable.
I have several tasks for next week besides getting the browse feature working. I'm making an "advanced" menu where such variable as buffer size and which weighting equation is used can be changed. I'm updating the readme and help files. I'll be doing a lot of general cleanup to make everything neat.
I'd also like to scale the magnitudes so they are between 0 and 1, but this caused problems when I briefly tried this because too many values were too close to 0 and were discarded.
And, of course, some screenshots:
See you Monday.
I then spent all day making a browse option, or trying to. It doesn't work as of yet. The idea is that you should be able to use any sound file from anywhere on the computer, so I'm making a window that is like any Open Document GUI. It shows the directory and you can open or collapse folders and select the desired file and use that one. There are two problems with this. First, it prints the whole pathname of each file or folder which makes it too long to practically read, but JTree names it using File.toString() so I need to find a way print only the end of the pathname. The other problem is that this only works once. If you click browse and chose a filename that works fine, but try to do it again without restarting the program and it gets NullPointerExceptions.
While showing the professor how the GUI works, I found why my code has been printing a lot less than it used to. Where I get the dB of the file, I've been multiplying by 0.775 instead of dividing. This hasn't been not on files such as a440 because 0.775 is close enough to 1 that it didn't make a difference. On full songs though, it was very noticeable.
I have several tasks for next week besides getting the browse feature working. I'm making an "advanced" menu where such variable as buffer size and which weighting equation is used can be changed. I'm updating the readme and help files. I'll be doing a lot of general cleanup to make everything neat.
I'd also like to scale the magnitudes so they are between 0 and 1, but this caused problems when I briefly tried this because too many values were too close to 0 and were discarded.
And, of course, some screenshots:
 Maple Leaf Rag
 Granular Roads Creatovox
See you Monday.
08 July, 2010
Axtell's Notes: July 8
I got a bunch of small problems fixed today, finished up my window research and continued to write the readme and help files.
I finally figured out how to change the heap size! Excellent. When calling the GUI, instead of calling "java BigGUI" I now call "java -Xmx(heapsize)m BigGUI" I've been using 512 megabytes and haven't had an OutOfMemoryError all day.
Everything can now work with an .au, .aif, or .wav file now. I'm looking into getting it to work with .mp3's too, but I'm not sure how possible that is.
I reactivated NoteFinder. It had been commented out about a week ago to try and avoid the memory problems, and I then forgot where it had been commented out.
All the windows are scaled to the same range of points (magnitudes = 0-3.5).
Oh man, It's been a while since I've posted some screenshots. Here's Maple Leaf Rag with several different windows:
 Unwindowed Maple Leaf Rag
 Maple Leaf Rag - Gaussian
 Maple Leaf Rag - Blackman
 Maple Leaf Rag - Blackman-Harris
I seem to be missing a lot of bass notes from this. I'm going to look at a bunch of full-length songs tomorrow to find out what needs to be fixed. Also, ThunderIntro is still missing the claps, and ShaveAndAHaircut is missing the cymbal crash. I'm going to look into finding those tomorrow too.
Axtell's Notes: Windows
So I've been doing some research into windowing; which is better for what type of sound and so on. There is no window that is universally the best so, we have to decide what window to use depending on what information we want to get from a sound and what kind of sound it is. As a general rule, the more complicated a window is, the more accurate it is.
Some variables that we look at are:
-Highest side-lobe level; low levels reduce bias
-Worst-case processing loss; low levels increase detectability of peaks
-Quality of frequency resolution
-Amount of spectral leakage
-Amplitude Accuracy
Rectangular (none) has the highest side-lobe levels (~-13dB) and a lot of spectral leakage and very bad amplitude accuracy. It is best used with a transient (e.g. spoken word) shorter than the window or two close frequencies of almost equal amplitudes.
Bartlett also has high side-lobe levels and the leakage and amplitude accuracy is only a bit better.
Hanning and Hamming are good choices for a fast, general-purpose window. They have good frequency resolution, get rid of a fair amount of leakage and don't take forever to calculate. Hamming window is our current default.
Gaussian windows have the added benefit of a variable that adjusts the side-lobe level and processing loss to a point. It is best used with longer transients.
Flat-Top has very low processing loss so is best used when amplitude accuracy is important.
Blackman and 4-term Blackman-Harris are the best at reducing spectral leakage and also have good amplitude accuracy. They have very low side-lobe levels. They are best for general use when speed is not necessary. These have a tendency to push the memory over its limit right now which is why we don't use them for full length songs as often.
07 July, 2010
7/7/10 Daily Journal of AT
Well, did some more testing today, and managed to fix two of the things I wanted to.
First, when graphing the data generated by the FFT, lately the higher peaks have been lost (namely cymbal hits). This is more than an asthetic concern, as if those notes aren't graphed, it means they aren't being returned by the threshold cleaning function. I experimented with a few of the variables in there, and managed (in the Hamming window, at least) to get the cymbal hits in a few test files to show up. Amusingly, since the beat finder function gets the data before it's cleaned, it has no problem finding cymbal hits, so there were cases where there was a beat for no notes shown.
I didn't actually solve that problem, but with Axtell's new windows, I'm confident that they will take care of the problem. I also improved the beat finder so that it returns more accurate beats. Before, all beats were returned, and I was playing with returning no beats if one was found within a partial second of it (because it wasn't a new beat, mearly the old one continuing). Now, I've added a portion to the cleaner that checks to see if the previous bit was a beat or not. If it is, it is assumed that the beat is not a new one, and sets it to false. To see how this affects the two strong-beat songs:
Sweet Caroline (techno remix)

My Sharona (rock remix)

At top is the song, then the uncleaned beats. After that is beats cleaned by closeness (i.e. if they have a previous true, they're not a beat), beats cleaned by the .1 sec rule from yesterday, and then both cleanings together. They tend to compensate for each other's failings, so it will be kept as is.
With that, I can say that the Beat Finder is done. There is the option to add in cymbal finders, but all that takes is testing to find the correct band. I won't be in tomorrow or Friday, unfortunately, but when I get back, I plan on working on improving the threshold cleaner for the data.
Axtell's Notes: July 7
We made a lot of progress today. Everything is running about as fast as it did last week. This is because of two changes: first, I modified Gregor's FFT and bitReverse methods to work with a 2D array of doubles instead of Complex (we're now using that instead of Sonogram's code), and second, I moved getWindowed (the actual math of the windows) from the enum Window to FFT.
All the windows (none, Bartlett, Hamming, Hann, Gaussian, Blackman, Blackman-Harris and Flat-Top) are working now. The problem with Blackman-Harris and Flat-Top was that they need to use indexes -N/2 < i < N/2 (Where N is the number of samples and i is the index.) All the other windows use 0 < i < N. The windowed data also scales so that the highest point is always the same. This is so the colors and what prints is consistent.
I've been doing some research into which windows are best for which kinds of sound. Tomorrow's post will explain that once I've had a chance to compile all the information I've found.
We're running out of memory very often still. I've added a popup window to explain what's happened and to stop it from printing the error in the terminal, but we haven't found a way to fix it. It happens mostly with the Blackman-Harris window when running anything longer than ten seconds.
I've started writing the Read Me for the whole program and realised that we don't have a name for our program. For now we're calling it BUFFET (Big Useful Fast Fourier Epic Transform.) That is subject to change.
06 July, 2010
7/6/10 Daily Journal of AT
Well, I've got more to show for my efforts today, even if they're all in picture form.
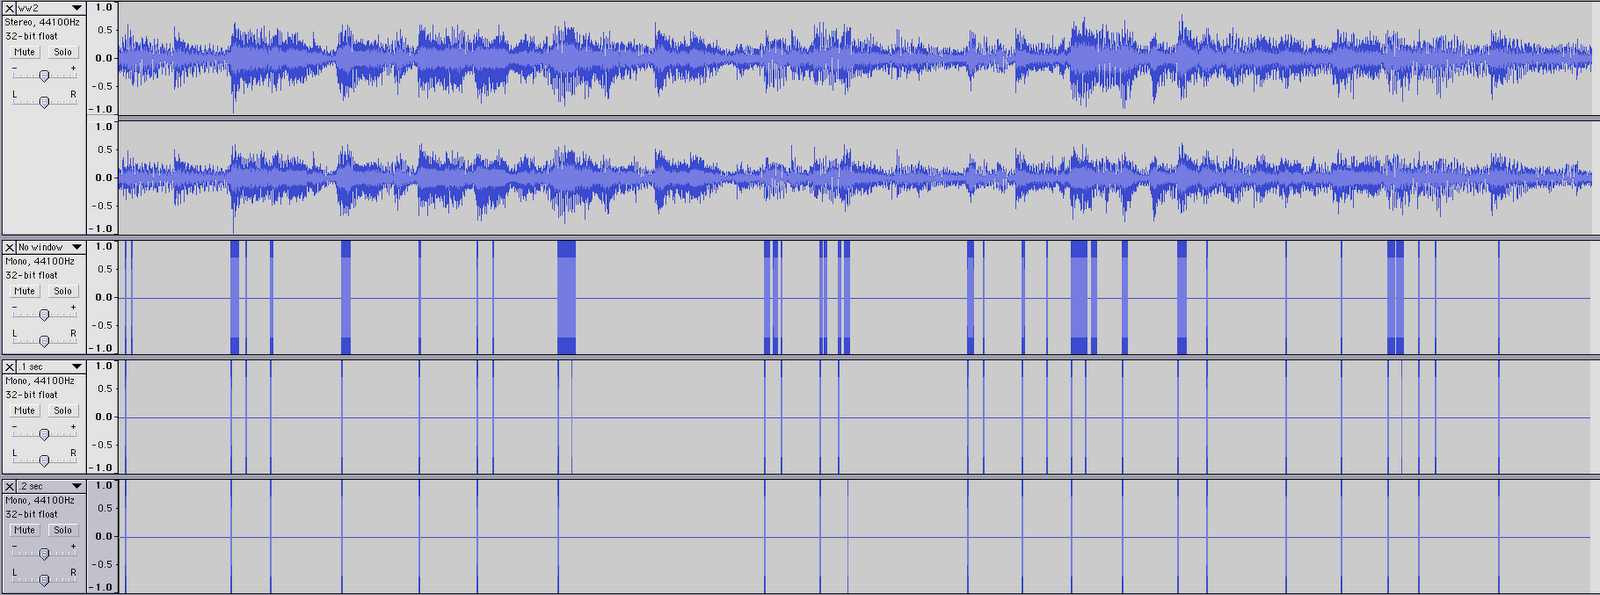
I started today by trying to get the BeatFinder to be more consistent. I ended up abandoning the function that finds the proper multiplier based on surrounding loudness, as it only ended up deleting all useful data. I decided on a base multiplier of 1.1 times the average as the threshold for a beat, as anything more started cutting out actual peaks. I stuck with base beats only today, and analyzed a few different songs. I also wrote a "cleaning" function for the beats. Basically, as it is now, if there is a hit on a base drum (or a really low base guitar note), the function registers it as a beat. It takes samples every portion of a second, so naturally, if one note lasts for a quarter not span, it will return a lot of "beats" in a row, rather than just one. I used four different songs (Sweet Caroline remix, My Sharona, Wild World, and Maple Leaf Rag) that had four different strengths of back beats (strong, moderate, weak, and none, respectively). I ran them with no cleaning, .1 second cleaning, and .2 second cleaning. These are the results:
Sweet Caroline (techno remix)

My Sharona (acordian rock remix)

Wild World (original country)

Maple Leaf Rag (piano only)

Looking at them through Audacity, it becomes much easier to see and compare how each cleaning function is doing. At the top of each image is the sample of the song being played, then the uncleaned beats, the .1 sec cleaned beats, and the .2 second cleaned beats.
With the steady techno beat, no beats are lost in the .2 sec cleaning, and the .1 cleaning leaves them messier than they should be (if we want one beat in the file for each actual beat). However, such a rigourous cleaning causes the rock song to lose notes. With the slower country, it's not as apparent either way, and the acoustic piano shouldn't bet getting very strong peaks (it probably has a few from low notes, resonance, and a bit of spill). In any event, depending on which kind of music is being analyzed (namely, slow or fast, loud or soft) would determine which cleaner would be more useful. As the computer should be (eventually) able to decide this on it's own when running the program, I left the second length as a changable variable.
In other news, the power briefly went out today. Fortunately, I saved recently enough that no work was lost.
I started today by trying to get the BeatFinder to be more consistent. I ended up abandoning the function that finds the proper multiplier based on surrounding loudness, as it only ended up deleting all useful data. I decided on a base multiplier of 1.1 times the average as the threshold for a beat, as anything more started cutting out actual peaks. I stuck with base beats only today, and analyzed a few different songs. I also wrote a "cleaning" function for the beats. Basically, as it is now, if there is a hit on a base drum (or a really low base guitar note), the function registers it as a beat. It takes samples every portion of a second, so naturally, if one note lasts for a quarter not span, it will return a lot of "beats" in a row, rather than just one. I used four different songs (Sweet Caroline remix, My Sharona, Wild World, and Maple Leaf Rag) that had four different strengths of back beats (strong, moderate, weak, and none, respectively). I ran them with no cleaning, .1 second cleaning, and .2 second cleaning. These are the results:
Sweet Caroline (techno remix)

My Sharona (acordian rock remix)

Wild World (original country)
Maple Leaf Rag (piano only)

Looking at them through Audacity, it becomes much easier to see and compare how each cleaning function is doing. At the top of each image is the sample of the song being played, then the uncleaned beats, the .1 sec cleaned beats, and the .2 second cleaned beats.
With the steady techno beat, no beats are lost in the .2 sec cleaning, and the .1 cleaning leaves them messier than they should be (if we want one beat in the file for each actual beat). However, such a rigourous cleaning causes the rock song to lose notes. With the slower country, it's not as apparent either way, and the acoustic piano shouldn't bet getting very strong peaks (it probably has a few from low notes, resonance, and a bit of spill). In any event, depending on which kind of music is being analyzed (namely, slow or fast, loud or soft) would determine which cleaner would be more useful. As the computer should be (eventually) able to decide this on it's own when running the program, I left the second length as a changable variable.
In other news, the power briefly went out today. Fortunately, I saved recently enough that no work was lost.
Daily Blog 7
Today I spent the day trying to further decipher the constant Q transform. I looked at Judy Brown's MatLab code for the "brute force" method of calculating the CQT. I tried to translate it into java but the translation proved more difficult than I originally thought so I decided to re-read her paper on an efficient algorithm to calculate the CQT.
I had a little more success with understanding the CQT by re-reading the paper. I think I have a good idea of what the transform does and what variables are used to calculate the transform. Tomorrow I plan on trying to get a working program to calculate the spectral kernel for the transform. After calculating the spectral kernel, the CQT is found through a simple multiplication.
I had a little more success with understanding the CQT by re-reading the paper. I think I have a good idea of what the transform does and what variables are used to calculate the transform. Tomorrow I plan on trying to get a working program to calculate the spectral kernel for the transform. After calculating the spectral kernel, the CQT is found through a simple multiplication.
Axtell's Notes: July 6
Today I made an enum class for the windows. This cleaned up the code a lot, but also slowed it down. We're also still get OutOfMemoryErrors.
The enum class Windows has 10 windows right now: rectangular (un-windowed), Bartlett, Hamming, Hann, Gaussian, Blackman, Blackman-Harris, Flat-Top and Tukey. I had a Kaiser-Bessel window as well, but that uses infinite series and that was taking much too long to calculate. I'm going to look into which ones we don't need or won't get used so we don't have anything unnecessary in the code.
Speaking of unnecessary, I meant to go through all my code and make sure that every class only imported what it needed, but I didn't get to it today. I hope that will help to stop the code from using too much memory.
I did some research into which windows are better for different kinds of sound files and which return more precise results. It looks like Blackman (or Blackman-Harris), Gaussian, Flat-top and Hamming are the best depending on what kind of sound is used.
Lots of testing today without any definitive results yet, so I don't have much to say. I'll be doing more of the same tomorrow as well as cleaning up.
02 July, 2010
7/2/10 Daily Journal of AT
Today was kind of slow. Primarily, it was spent testing different multipliers and size ranges for the Beat Finder. The multiplier is how the threshold for determining whether something is a beat or not is found (if the given data is higher than the average times the multiplier, it's a beat). The tutorial I found said that the most reliable multiplier is within a function relating to variance, but after getting a lot of screwy data, I decided to work with a base multiplier for now. Trouble is, it works differently on different files. With something with a strong base beat, like the Thunder intro, it does quite well, but on anything with a more even sound, it usually doesn't pick up the beats.
I was able to successfully implement the Bark sizing to the frequencies. Previously, when I wanted to find the beat in a given range of hertz, I used a multiplier, which worked well on low frequencies, and poorly on high ones. The Bark sizing works on a semi-logarithmic scaling, so low ranges are still accurate, but high ones can also be found. For example, here's the base beat of Thunder Intro:

The handclaps are still imperceptible ):
We also tried putting together our GUI and FFTs, and found out that we don't actually know what the height of the peaks is in, other than relative loudness. Presumably, since we're using the magnitude rather than the direct data, there is not necessarily any correlation between heights, volts, or decibels, other than relatively.
Axtell's Notes: July 2
The Gaussian window now can be called from anything without crashing, but is not the correct equation for that window. I'll be spending some time this weekend looking for the correct equation and at some other windows that could be better than Hamming.
I got Gregor's code working with Tayloe's and mine, but it seems to return a lot less data than our FFT. I got frustrated trying to figure out the difference since the math is almost exactly the same, so I am going to come back to that on Tuesday.
I was reading about using an overlap to get more accurate data. Overlap meaning that, when we split the wav into samples, we take each sample starting halfway through the last one. Example: If the length of each sample is 1028, each sample starts 512 after the one before it did. This way any data that would be lost because the splits are right on a peak aren't lost. This also means that we are making an array twice as long and we're getting OutOfMemoryErrors again. Clearly, we either need to find a way to use less of the heap, or I need to actually raise the heap size to match our needs.
After a long weekend of window research I will be adding new windows and making the Gaussian window work, looking at the Complex FFT again to see what's going on there, and boosting the java heap size or cleaning up our code to use less space.
Have a good Fourth of July!
01 July, 2010
Daily Blog 6
It's been slow going the past few days. I decided to create a new class in hopes it will help clean up the code in the FFT and, since the constant Q transform uses many of the same methods and calculations as the FFT, I thought a new class would help. Writing the new class was the easy part but translating my existing program to use the new class proved to be more difficult than it should have been. After eliminating all of the syntax errors, I started receiving null pointer errors followed by FFT output discrepancies. After a day and a half of debugging, I was able to figure out my problems laid in the fact I neglected to initialize a field I called later in the program and I was not deep copying my temporary variables in my bit reverse function.
After finally getting the program to work again, I started working on implementing a Gaussian windowing function which is almost done and should be complete tomorrow morning. I will then start recoding the constant Q as I had started it a few days ago but need to implement it using the new class.
After finally getting the program to work again, I started working on implementing a Gaussian windowing function which is almost done and should be complete tomorrow morning. I will then start recoding the constant Q as I had started it a few days ago but need to implement it using the new class.
7/1/10 Daily Journal of AT
First day of July, and I feel like we're getting things done. (Which is good, since we're nearing the end of week 5.)
Started today by working with BeatFinder to speed it up. Since there was no way I could get the file reading to go any faster, I started playing with different ways to pass the data from FFT to BeatFinder. I ended up re-writing BeatFinder as a class, with accessors, that was given each miniwave FFT data as it was read. After all the FFTs were done, it runs itself to get the beats. If, for some reason, this is done when there is no FFT data, it gets beat information directly from the file (as it did in the original function from the begining of the week).
While I was working in WaveSplitter (which is where FFT, PeakFinder, and BeatFinder are all called) I realized that we didn't need to create miniwave files and save them to disk. Instead, the miniwaves are passed directly to FFT, without writing them to the disk. This nearly halfs the time when running large files, which is great, but makes us unable to run a single FFT on a given second. If there's time, we'll work on getting just the data at that second to find a single FFT, or we'll just abandon it (as it's not terribly important except as a check or as a curiosity).
This afternoon was less interesting, as I've been testing various variables in the BeatFinder in order to better find beats. So far, I've gotten fairly reliable data concerning bass beats, although low notes from non-drums are also included, and vocal sound can throw it off. Tomorrow is more work on that, and I hope to have it working reliably soon.
Axtell's Notes: July 1
Very slow day. I first played with raising the threshold a little bit to see if I could clean up the peak graph at all, but it cut out too much data. I read a paper from ircam in France on spectral features. I looked at Gregor's FFT code that uses complex arrays instead of doubles to see how much work it would take to start using that instead of what we have now. There are basically two ways to adapt everything to work together. We could either get all the FFT data in a complex array, read just the real part as doubles into a double array that could be used in everything Tayloe and I have written, or we could adapt everything we have to work with a complex array. We're not sure which will work the best. We're going to try both tomorrow. I spent the rest of the morning trying to get rid of the miniwav's, but Tayloe's worked better so I scrapped that. We no longer use miniwavs at all. Maple Leaf Rag finishes in just over two minutes on our fastest computer now. It used to take 10-15.
In the afternoon, I fixed the colors again. Someday I'll be done fixing the colors. Now the colors are printed in order from quietest to loudest because the quieter peaks were covering up the louder peaks and making everything harder to read accurately.
Lastly, I worked on adding a Gaussian window because it is supposed to work better than the Hamming window which is out current default. That is almost working, though not at all in FFTGUI. In fact, FFTGUI doesn't work right now because I haven't had a chance to update it to deal with the added window.
So, first task tomorrow is getting FFTGUI working with Gaussian windows and making sure that my Gaussian window works. Then I will move on to switching our code from the old FFT class to Gregor's.
30 June, 2010
6/30/10 Daily Journal of AT
Spent the morning figuring out things going wrong with the FFT version of BeatFinder. I managed to get an analysis working on bands of frequencies, rather than just one, so that it was more accurate. However, re-reading my notes, I realized I forgot something critical: the imaginary aspect. Fairly easy to do, since our FFT discards the data entirely. According to the algorithm, the data should be squared, and in the case of FFT data, the imaginary squared is subtracted from the real squared, leading to a very large difference in data. I'm not 100% sure this is necessary, as we use the real data only in everything else. However, this might cause different errors that we are not aware of .
Moved onto/got distracted by Axtell's work with thresholds of hearing. Basically, depending on frequency, the softest note people can hear changes. There are a few algorithms that approximate this threshold, and we worked with them today to replace PeakFinder, as it did the same thing, only better. (This was the magic threshold I was searching for those two weeks ago!) Between the testing and debugging, that took most of the rest of today.
In the afternoon, I did some research to try and speed up the BeatFinder. I started out looking at ways to optimize the speed of the file reading, as that's where most of the lag comes from. Unfortunately, it seems that what I'm doing now is the fastest that it can get, at least in terms of accessing the file. It recommended using buffers (I am) and only getting necessary data (I do).
Alternatively, I could forgo writing all the FFT data (probably wise, as it's a very large file). The options then are (1) use the peaks instead or (2) get the beats as the FFT runs. The problem with the first is that I'm still not sure if it's returning all hearable notes, and, if it's not, it will throw off all the beats. The problem with the second is mainly one of structuring, as I'm sure it would be much faster then what I currently have (no reading or writing of files necessary!). I'll try implementing the latter tomorrow.
Axtell's Notes: June 30
So today we changed everything. Not quite, but it feels like it because we no longer use PeakData at all. Threshold has completely replaced it. I found the problems that were holding up Threshold (using the negative of the dB of that point for some reason...) and did a lot of testing as to which weighting function works best (A, B, C, D.) I also tried a slight shift on the decibel calculation when using A-, B- and C-Weightings because their functions use a shift to line up their numbers (Remember, none of these functions are perfect because no one has yet found an equation to match the ATH data set.)
I looked at four files (a440.wav, threenotes.wav, fade.wav and mapleleafrag.wav) with each weighting with and without the shift. (All images are of fade.wav)
A-Weighting lost a lot of data that was audible:
B-Weighting shows the most data without showing spill:
C-Weighting was a close second to B:
D-Weighting shows a lot of upper frequency spill, just barely visible here:
So B without a shift was the winner and now our default weighing function. Here is Maple Leaf Rag using our new and improved Threshold:
Compare that to this, the last Maple Leaf Rag I posted from June 25th:
We gained some upper frequency spill, and lost a lot of lower frequency spill. I'll try to clean that up some more tomorrow.
I also did a little bit of updates to the color spectrum to work with Threshold. Tomorrow, I'll be adding decibels everywhere since we have that math working now! Finally.
I looked at four files (a440.wav, threenotes.wav, fade.wav and mapleleafrag.wav) with each weighting with and without the shift. (All images are of fade.wav)
A-Weighting lost a lot of data that was audible:
B-Weighting shows the most data without showing spill:
 Fade.wav - A-Weighting
 Fade.wav - B-Weighting
C-Weighting was a close second to B:
D-Weighting shows a lot of upper frequency spill, just barely visible here:
 Fade.wav - C-Weighting
 Fade.wav D-Weighting
So B without a shift was the winner and now our default weighing function. Here is Maple Leaf Rag using our new and improved Threshold:
Compare that to this, the last Maple Leaf Rag I posted from June 25th:
 Maple Leaf Rag
 Maple Leaf Rag - June 25
We gained some upper frequency spill, and lost a lot of lower frequency spill. I'll try to clean that up some more tomorrow.
I also did a little bit of updates to the color spectrum to work with Threshold. Tomorrow, I'll be adding decibels everywhere since we have that math working now! Finally.
29 June, 2010
Daily Blog 5
I started researching the constant Q transform (CQT) on Monday and found the transform differs from the discrete Fourier transform (DFT) in several ways but the most important difference is the constant Q transform analyzes an audio file on a logarithmic scale. At the lower frequencies, there are more "bins" for analysis than at the higher frequencies. The file is analyzed this way because humans can not distinguish a 2.5 Hz difference at higher frequencies but we can at the lower ones so the resolution of the window at the high frequencies (10 KHz to 20KHz) does not have to be as high as at the lower frequencies.
Like the DFT, the CQT can be calculated by brute force or a short cut can be used. The fast Fourier transform (FFT) is the short cut for the DFT. The FFT is used in the short cut for the CQT. The CQT is equal to multiplying the FFT by the spectral kernel of the data. I found a website with some sample code in MatLab: http://www.hans.fugal.net/research/cq-octave.
Yesterday, I spent most of the day rewriting some of my previous code in hopes of condensing and modifying it so I could use a generic class for both my DFT class and CQT class. Unfortunately, I only managed to crash what I had written so I am going to change it back and look to modify it after I have a working CQT.
Subscribe to:
Posts (Atom)